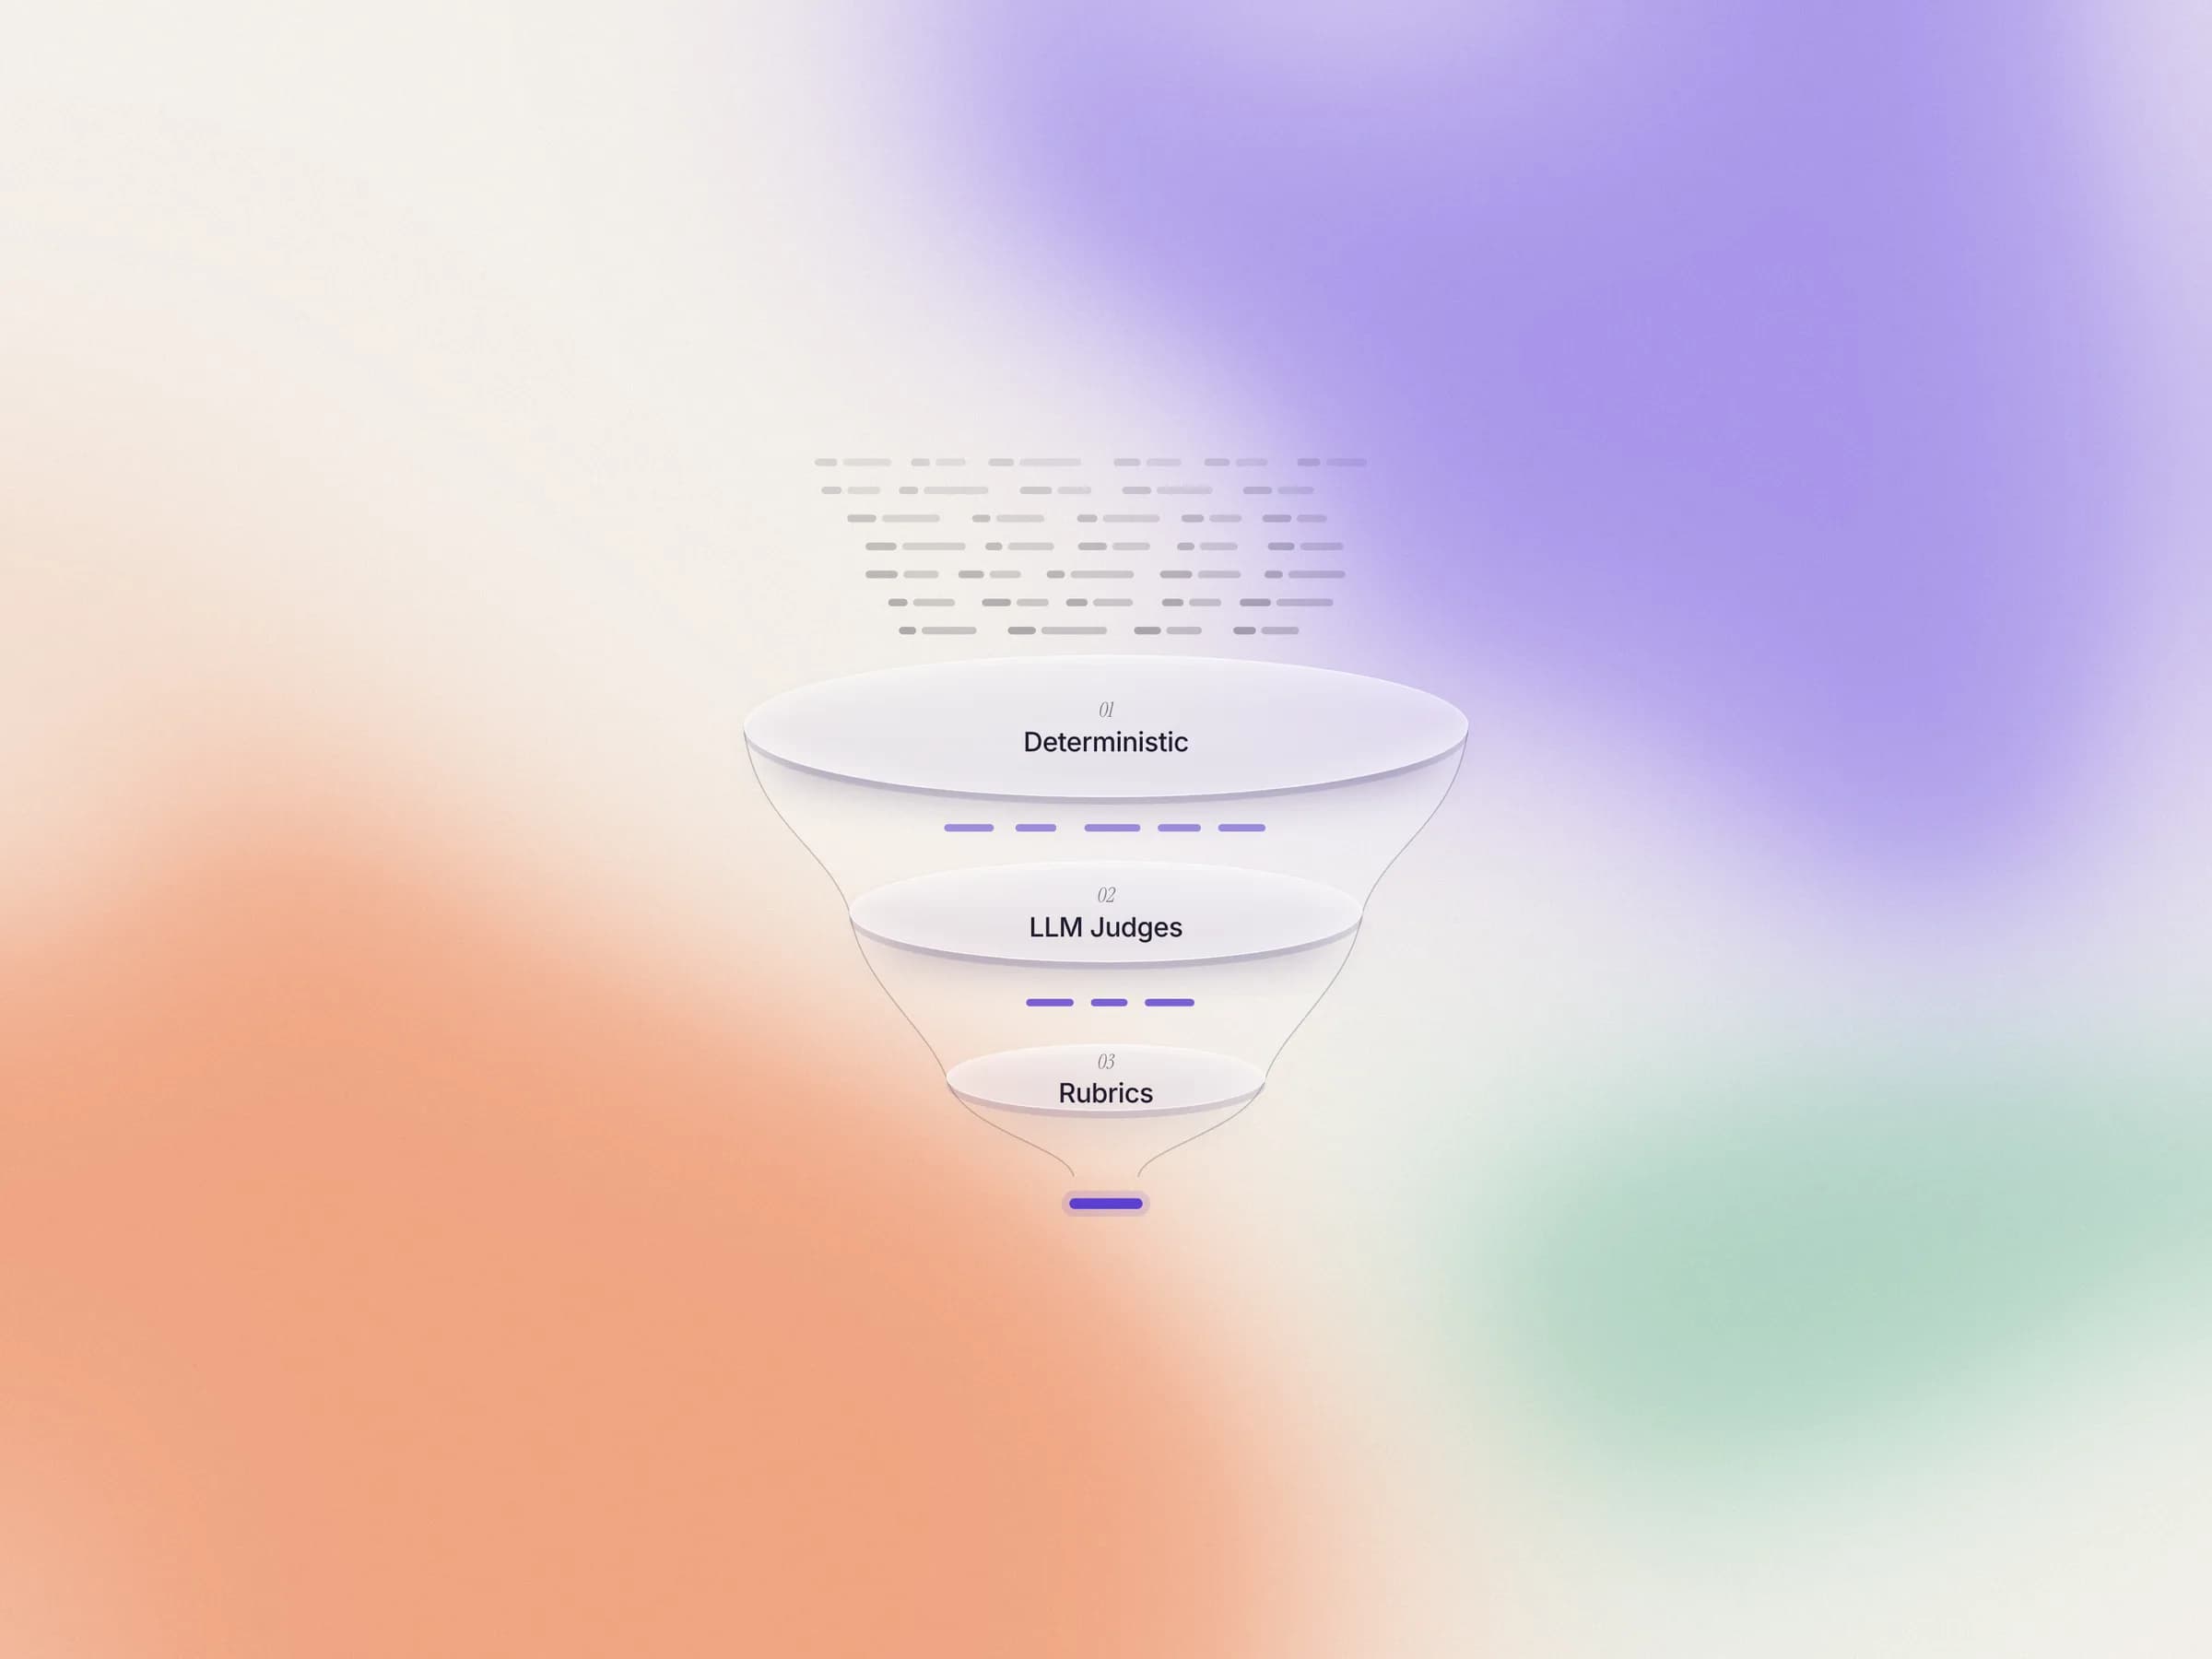
This post walks through how BEval Studio scores production LLM outputs. It covers the three evaluation layers, what each one costs, how sampling decides which logs reach an LLM judge, and what the results look like in the dashboard.
Why one evaluation method isn't enough
Teams monitoring LLMs in production usually fall into one of two traps.
Vibes-based monitoring. Someone spot-checks a handful of outputs each week, flags the obviously bad ones, and assumes the rest are fine. When this stops working, the failure has usually been compounding silently for days.
Judging everything with an LLM. Every output goes to another model for scoring. It's expensive, slow, and adds latency to the feedback loop. It also gives false coverage: a judge can miss the same systematic failure hundreds of times if nobody prompted it to look for it.
BEval Studio runs evaluation in three layers instead, each with a different cost and coverage profile.
| Layer | Runs on | LLM cost | Catches |
|---|---|---|---|
| Deterministic checks | Every log, synchronously | None | Structural failures |
| LLM judges | Sampled logs, asynchronously | Sampled logs only | Hallucination, dropped fields, wrong values |
| Custom rubrics | Logs or eval runs with a rubric attached | Scored alongside judges | Your own criteria |
Layer 1: Deterministic checks
This layer runs synchronously on every log at ingest, with no model call. The checks:
- Required fields: did the model return every field your schema expects?
- Types: is
date_of_birthactually a date, or a string like "around 1985"? - Date format: YYYY-MM-DD, not "March 12th" or "12/03/85".
- Empty arrays: the model says it found items, but the array is empty.
- Plausibility: an extracted age of 847, or a date in 2089.
- Empty strings: fields that exist but contain nothing useful.
The output is a deterministic score (det_score, 0.0 to 1.0) and a pass/fail breakdown per check. Results show up in the dashboard right away, with no queue and no cost.
This layer catches more than you'd expect. Most teams we work with find that 30-50% of their quality issues are structural, not semantic. A missing field or a malformed date is a hard failure that breaks downstream systems, so catching it on every log comes first.
Layer 2: LLM judges
Sampling
Not every log needs a judge. Most outputs are fine, and judging all of them is wasted spend. The sampling logic sends a log to judges when:
- the deterministic checks failed (
det_passed == false), or det_scoreis below 0.9, or- it lands in a random 2% baseline sample of structurally clean logs, for drift detection.
The baseline rate is configurable per tenant, so you can set 5% or 10% instead. Judge spend goes to the outputs that need scrutiny, plus a random sample to catch drift.
What judges score
By default, judges score three dimensions:
| Dimension | Question |
|---|---|
| Hallucination | Can each extracted value be traced to the source input, or did the model invent it? |
| Completeness | Did the model capture everything in the source, or silently drop fields? |
| Semantic accuracy | Are the values correct: the right date, the right amount, the right category? |
Each dimension gets a score and a reasoning trace. In the log detail view they appear as expandable rows with score bars and the full explanation.
Judge configuration
The default judge model is Claude Haiku, fast and cheap enough for high-volume sampling. Each tenant can override it: pick a different model, change which dimensions are evaluated, or write a custom system prompt that fits your domain.
Layer 3: Custom rubrics
A rubric is a named, reusable set of evaluation criteria that you define:
Medical Extraction v1
├── Patient demographics correct  (weight: 0.3, passing: 0.8)
├── Medication list complete      (weight: 0.25, passing: 0.7)
├── Dates in correct format       (weight: 0.2, passing: 0.9)
├── No hallucinated conditions    (weight: 0.15, passing: 0.85)
└── Dosage values plausible       (weight: 0.1, passing: 0.8)
Each criterion has a weight (how much it matters relative to the others) and a passing threshold. When a rubric is attached to a log or an eval run, BEval scores the output against every criterion and returns a per-criterion breakdown with scores and reasoning.
Rubrics are tenant-scoped and managed from the Rubrics page in the dashboard, not in code. Create as many as you need: one per use case, per document type, or per model version under test. They're how your team's definition of "good" becomes an evaluation that runs automatically.
How the layers fit together
The layers run in sequence, not as alternatives. When a log is ingested:
- Deterministic checks run immediately. The response includes
det_scoreanddet_passed. - Sampling decides whether the log goes to judges. If it does, the judge task is queued and runs asynchronously in the background.
- If a rubric is attached (at ingest time or through an eval run), rubric scoring runs alongside the judge evaluation.
For every log, the dashboard shows:
- deterministic checks as a pass/fail list with flag details
- judge scores as horizontal bars per dimension, with expandable reasoning
- rubric results as per-criterion breakdowns with pass/fail indicators
The home dashboard aggregates all of it across your traffic: average det score, average judge score, rubric pass rates and failure type breakdowns, sliceable by timeframe.
A day in production
A typical day might look like this:
- 10,000 logs ingested, each with a deterministic result the moment it lands
- 400 logs sent to judges: 200 from failed det checks, 200 from the random sample
- all 400 judge evaluations finished within minutes
- the dashboard shows
det_scoredown 3% on onekindof log, which traces back to a prompt regression shipped that morning
Nobody reviewed logs by hand, and judges ran on 400 logs instead of 10,000. The dashboard surfaced the drop along with the dimension driving it (hallucination, completeness or accuracy).
Each layer targets a different failure class, and all three feed the same dashboard.
If you ship LLM outputs to production and want to see how this works on your system, book a call. We'll walk through BEval against your setup.