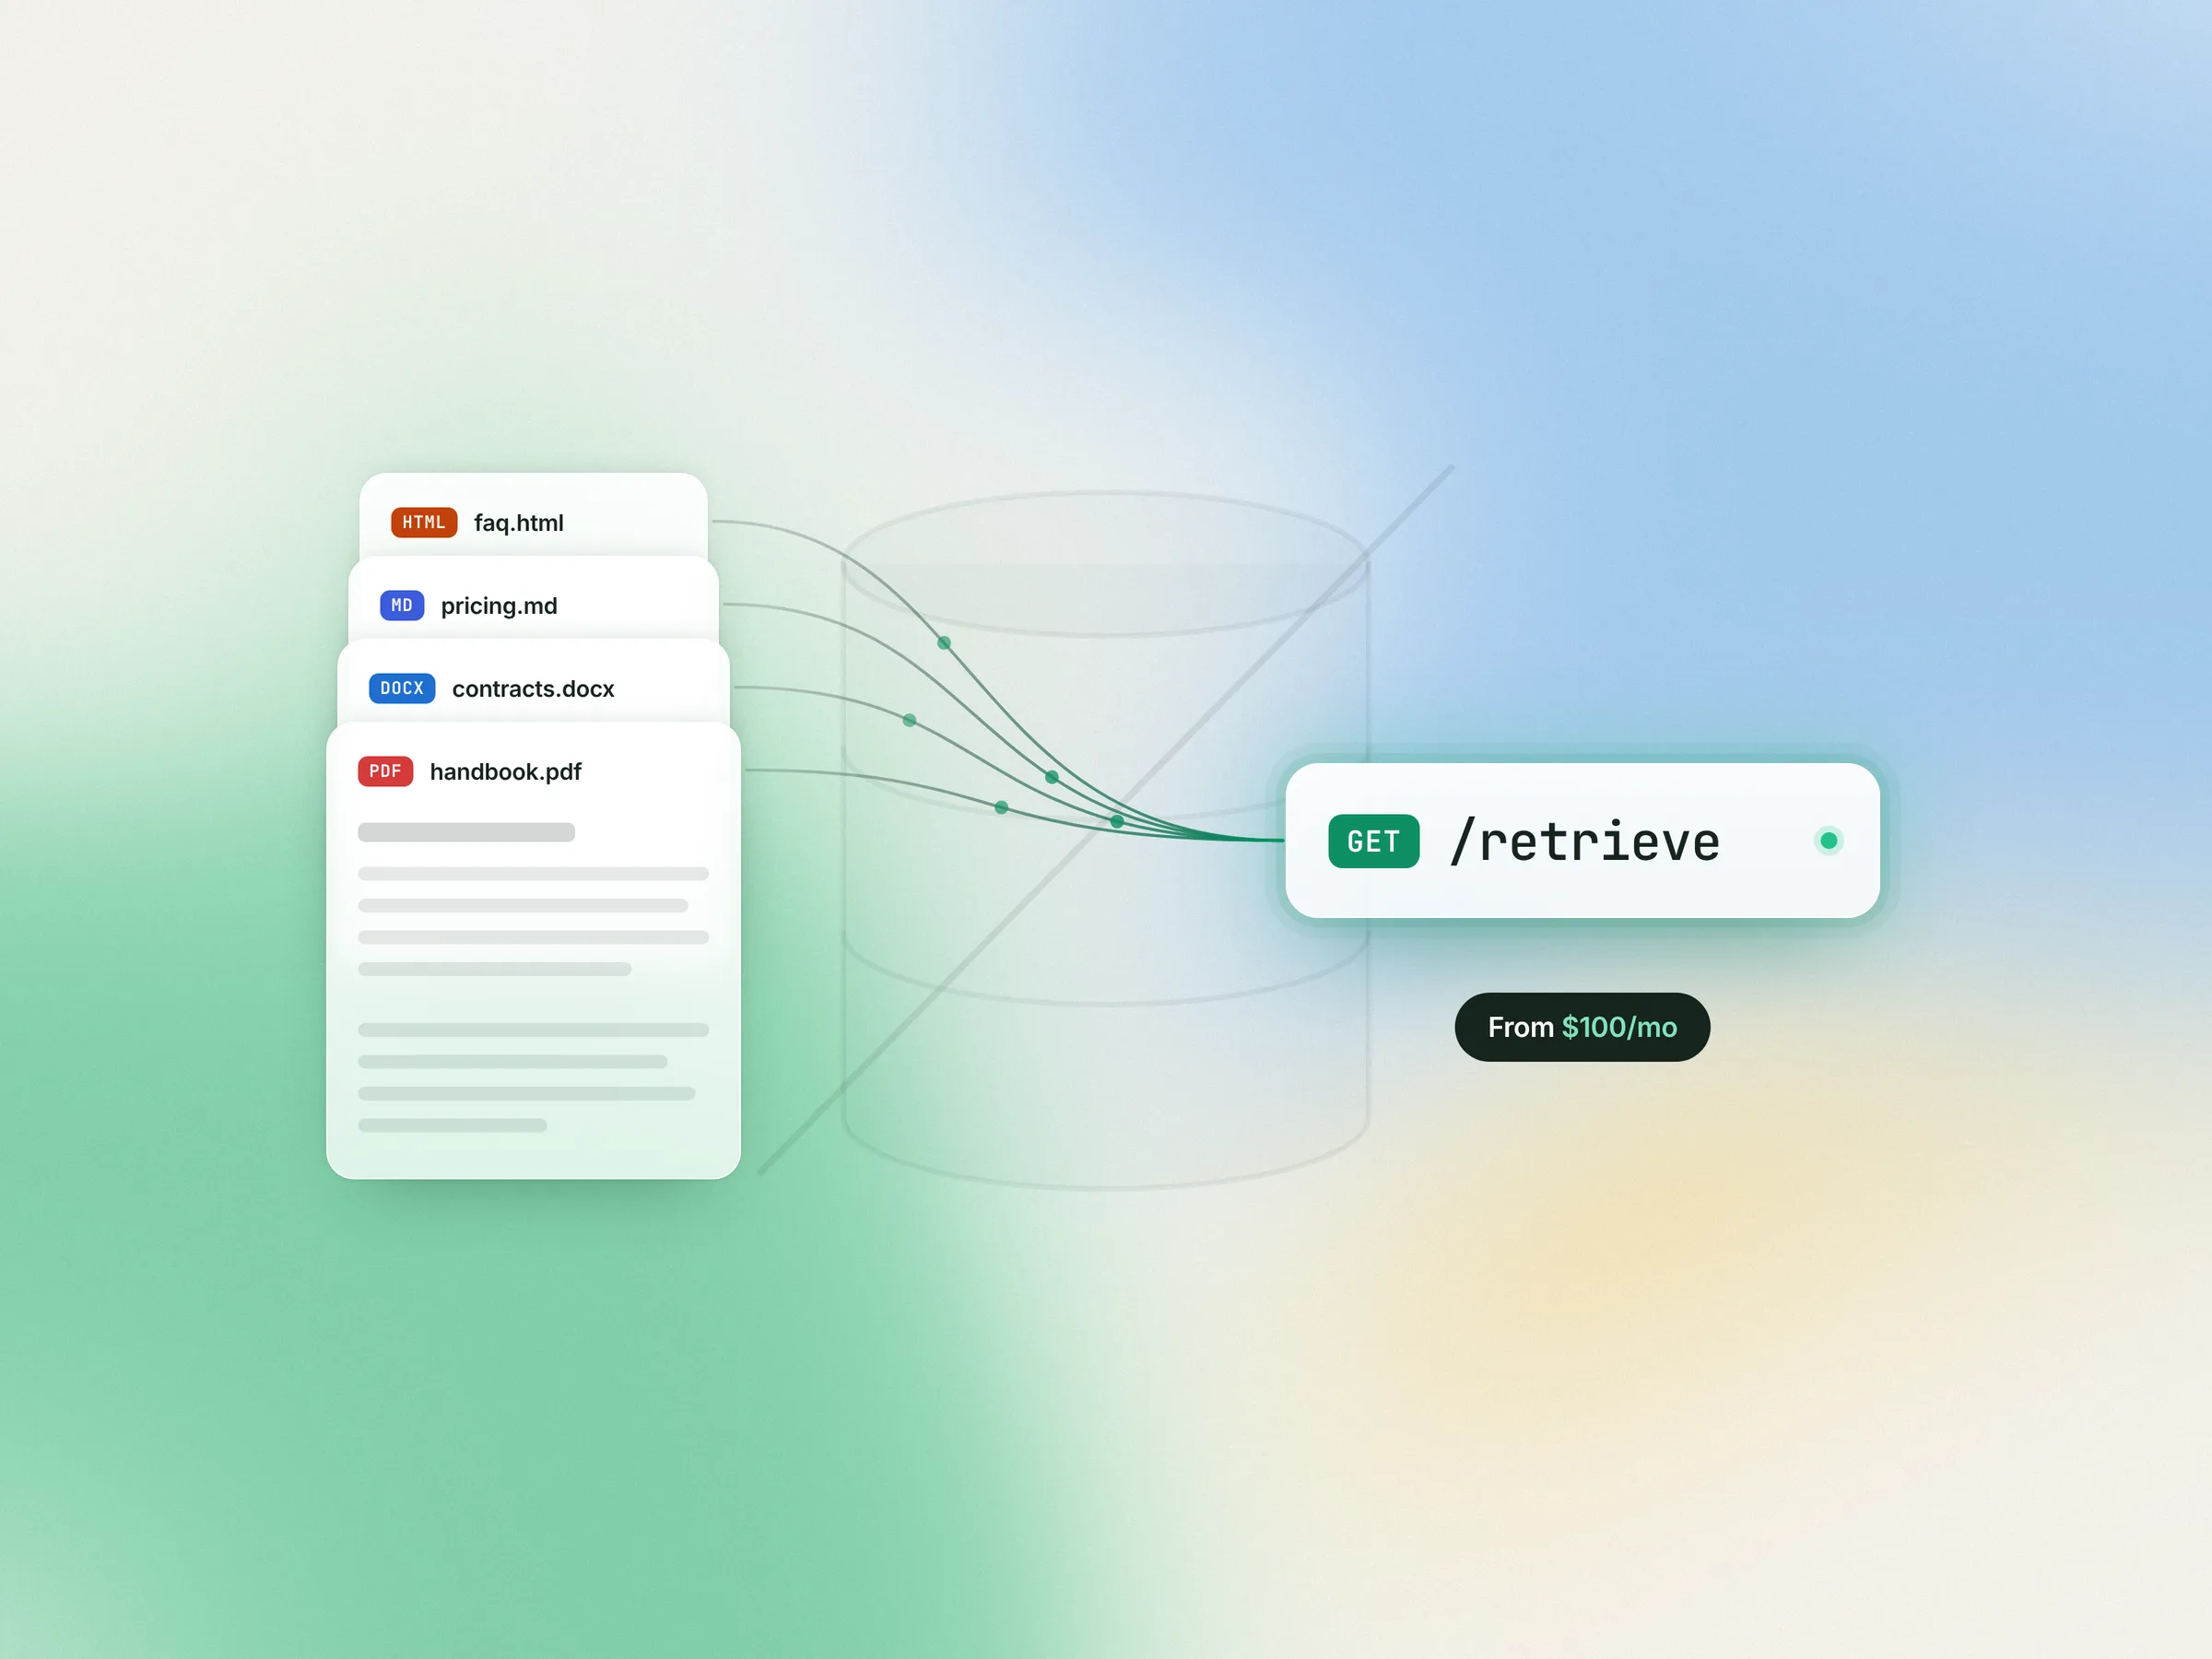
RAGista is our hosted RAG platform: you upload documents and get a retrieval API back. This post covers the problem it solves, how the pipeline works, how it handles Arabic, and what it costs, along with a self-hosted alternative.
RAG is an infrastructure project you didn't sign up for
Most teams that want RAG don't want to think about vector databases, embedding models, chunking strategies or hybrid retrieval. They want their LLM to have access to their documents and to get accurate answers back.
Building it from scratch means a long chain of infrastructure decisions before you can test whether any of it works:
- Which vector database?
- Which embedding model?
- How do you chunk a contract versus a policy document versus a court ruling?
- How do you handle Arabic?
- How do you notice when retrieval quality degrades?
These are real engineering problems. They're just not the ones you want to be solving. RAGista takes that stack off your plate.
What RAGista is
RAGista is RAG as a service. You bring your documents. We handle ingestion, chunking, embedding, retrieval, and the admin panel to manage it all.
You don't need to know which vector database runs underneath, and you don't configure an embedding model. You get an API endpoint that takes a query and returns grounded, cited answers drawn from your document corpus.
The admin panel lets your team manage that corpus without touching infrastructure or code. Upload new files, remove outdated ones, and see what was ingested and when.
How it works
1. Ingest your documents
Upload through the admin panel or push via API. RAGista parses PDF, DOCX, plain text and structured HTML, then chunks the content.
Chunking is structure-aware. It respects headings, clause boundaries and paragraph breaks instead of slicing at arbitrary token counts. This matters more than most people expect: bad chunking is a common root cause of retrieval failures that look like model failures.
2. Query
Your application sends a query to the RAGista API. RAGista runs hybrid retrieval (dense semantic search combined with sparse keyword search) and re-ranks the results before passing them to the LLM.
The response includes the answer and the source passages it was drawn from.
3. Monitor
The admin panel shows retrieval quality metrics so you can see when something degrades. For example, a new document type gets added that the retrieval pipeline wasn't tuned for.
For deeper evaluation, RAGista integrates with BEval Studio.
Arabic support
RAGista was built from the start to handle Arabic-language documents. Most off-the-shelf RAG tools handle them poorly, if at all.
Arabic makes retrieval harder in specific ways:
- Different tokenization behavior
- Right-to-left structure
- Dialect variation
- Legal and formal registers that don't match the training distribution of general-purpose embedding models
RAGista's chunking and retrieval pipeline is tuned for Arabic document types (legal texts, regulatory documents, enterprise agreements) as well as English and mixed-language corpora.
Judger, our Arabic legal chatbot for a Jordanian law firm, runs on RAGista. Its retrieval pipeline handles Jordanian court rulings and statutes in Arabic, with dialect-aware chunking and source citation on every answer.
Pricing
| RAGista (hosted) | Project kickstart (self-hosted) | |
|---|---|---|
| Price | $100 / month | $600 one-time |
| What you get | Admin panel access, up to 1 million tokens ingested, hosted retrieval API | Production-ready FastAPI RAG server, configured for your document types |
| Who runs it | We do | Your team |
| Ongoing dependency | Monthly platform | None after handoff |
RAGista: $100 / month
You don't think about infrastructure, and you scale up as your corpus grows. It's the right starting point for teams who want a production RAG system without building and maintaining the stack themselves.
The alternative: own the code
Some teams want to run the infrastructure themselves: full control over the stack, self-hosted, no monthly platform dependency. For them we offer a separate product, a $600 one-time project kickstart.
We hand off the FastAPI RAG server to your team to deploy and own. No monthly fee, and no dependency on us after handoff. It's for teams who want to build on a solid foundation rather than use a managed service.
If you have a document corpus and need accurate retrieval on top of it, book a scoping call. In 30 minutes we'll tell you whether RAGista is the right fit or the code kickstart makes more sense.